Friday, April 30, 2010

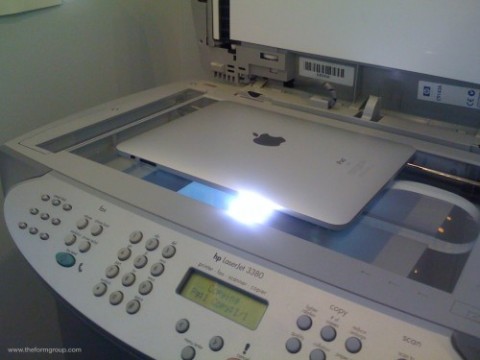
Evolution of Business Communication

Steps in corporate culture transformation:
  • Couriering around printed documents
  • Faxing documents to each other
  • Emailing documents as attachments
  • Emailing links to documents on sharepoint
  • Emailing links to enterprise wiki articles
  • Collaborating in the article and notified of changes via email
  • Collaborating in the article and seeing RSS updates in the enterprise portal

Also somewhere in there is the crazy scenario where I get email a PDF that was clearly created by someone who scanned a printed copy of a PowerPoint presentation.  I guess that worse, yet, would be a PDF created by scanning a printed copy of a wiki article.

Saturday, April 24, 2010

Complexity = Agile Simplicity

I'm a major advocate of traditional simplicity principles like KISS, YAGNI, DRY, the Unix Philosophy, etc.  I'm also very interested in complexity and solving large complex problems.  It occurred to me during an all day "fix this process problem" meeting today that the ideas of complexity and simplicity aren't actually antonyms.  Sure, by definition, they are, but I think the paradox in that comparison is that perhaps complexity can be defined as simplicity that changes over time.

My perception of complex problems is that given the examples of any one particular moment in time, the situation can be easily dissected, analyzed, documented, and understood.  Take a sample from the next moment in time and the same is true.  Try to combine that collection of understandings into a generalization that can be applied to other past and future points in time and the problem suddenly becomes complex.

One of the observations we get from agile development is that solutions will be more correct, given the flexibility to adjust to customer needs versus following a previously defined historical specification.  Agility is the ability to adjust to change.

Therefore, complex problems should be solvable by solutions that are simple and agile.  Solutions do not have to be complex.

We run into challenges designing agile solutions, though.  Many traditional solution design tools often call for static process flow diagrams, swim lane control charts, concrete data models, class diagrams, etc.  I think that some of the behavioral object oriented patterns give us some clues on how to introduce agility into solutions, but understanding when to apply those (and how to apply them within some technologies) takes creativity and experience. 

I think that introducing that same kind of solution agility into human processes is also very challenging.  Often, we want clearly defined instructions and flow charts to instruct individuals on exactly what to do.  The only variation being a Madlib style fill-in-the-blank.  Perhaps we need more "and then a miracle occurs" steps in our complex processes.  And perhaps that's both acceptable and desirable in some processes.

Sunday, April 18, 2010

Digging Holes

The following parable is adapted from one that I was forwarded by a friend this week...  It seemed a good analogy for a poor IT Service Management philosophy.


Two IT directors changed jobs and were working for the city public works department.  One would dig a hole and the other would follow behind her and fill  the hole in. They worked up one side of the street, then down the other, then  moved on to the next street, working furiously all day without rest, one director digging a hole, the other director filling it in again.

An onlooker was amazed at their hard work, but couldn't understand what they were doing. So he asked the hole digger, "I'm impressed by the effort you two are putting in to your work, but I don't get it -- why do you dig a hole, only to have your partner follow behind and fill it up again?"

The hole digger wiped her brow and sighed, "Well, I suppose it probably looks odd because we're normally a three-person team. But today the guy who plants the trees called in sick."

Sunday, April 11, 2010

Personal Best


Today's run...  The Go! St. Louis Half Marathon
My first official race!

Distance: 13.1 miles
Time: 2:34
Place: 7,520th

It was awesome!

Saturday, March 20, 2010

What's the gap?

At the office, we're working on a strategy around how we maintain and publish various types of technical information and instructions.  For instance, there's been a big emphasis around transition of system maintenance and support responsibility from project/implementation teams to support teams.  What kind of documentation is required?  Where should that documentation be stored?  What format?  Who should create it?  etc.

One of the big cultural battles has been a solution of MS Office documents and MS SharePoint versus MediaWiki.  It'll be obvious, but just to lay it out up front, I stand firmly on the MediaWiki side of this discussion. 

On the Office/Sharepoint side, you have an argument that "everyone knows how to use MS Office applications; cut and paste of screenshots is easy; you don't have to know how to program the wiki."

On the MediaWiki side, you have an argument that "Sharepoint organization doesn't make any sense; searching across different sites is awkward; you always have open a separate document in a separate application to see what you really want to see; and it just doesn't feel webby enough."

This argument from the SharePoint side that you have to program the wiki is the one their leadership is most adamant about.  "Our analysts aren't programmers," they say.  We're using a wysiwyg editor!  Is a little wikitext markup really programming?  I think the ability to pickup on a little wikitext is just like the ability to learn how to use formulas in MS Excel... and if you can't write a simple SUM() or =A1+B1 is MS Excel, then you don't have any business being in an IS job... or really any business support job for that matter.

Perhaps that's a strong statement, but I think that any IS person should feel comfortable picking up a little HTML or wikitext markup.  I often hold up my wife, an English major / office worker / writer, as an example of "if she can do it, then an IS person should be able to do it!"  But perhaps I'm looking at the wrong set of characteristics. 

Maybe the gap is a generational/cultural one rather than an educational/cultural one.  There's probably a more articulate way to describe that, but what I'm getting at is that my wife is also comfortable with blogging, Facebook, and the online / social community in general.  I wonder what percentage of people in the SharePoint camp are regular contributors to blogs, Facebook, Twitter, or other social networks?

What is the gap between someone who thinks the business world is a collection of MS Word documents and someone who things the world is a more directly accessible, public, and transparent collection of content?  And how do we get people across that gap?

Monday, February 8, 2010

Living on the Edge

I've been working for a while on explaining the value and importance of Enterprise Information Management.  While I usually get some good ideas from Wikipedia, the article there today has let me down.  As referenced in the Wikipedia article, Gartner and Forrester have some valuable things to say on the topic.  But I believe that it can really be boiled down to a simple and practical explanation, given one assumption: in a business organization with optimal management of information, no individual business unit will appear to be fully optimized even though the overall organization is optimized.  Here's why:

Imagine the information flow through the business units of an organization as a connected network of nodes.  Each edge in the graph represents some type of process (automated or manual) that moves information from one department to another.  The Information Supply Chain model describes how each of those edges has a cost associated with it.  Each edge, to be worth while, must also create some added value (either through reduced effort via automation or added meaning).  The cost / benefit sides of those edges, though, don't typically come from / contribute to the same departmental bottom line.  Typically it is a matter of the originating business unit paying the cost of additional data collection or manipulation so that a receiving business unit can benefit.


In the VERY simple diagram above, the argument is obvious.  The Admitting department in a hospital has the purpose of collecting information from a patient that other departments will need in order to do their job effectively.  Admitting collects patient information (e.g. contact information, primary care physician, insurance information) once so that other departments can all benefit from it.  Surgery uses the information collected during Admitting to retrieve the patient's medical record and orders.  Billing uses the same patient information plus the additional information about what procedures were performed by Surgery to create invoices to payers (who will use similar information to try to avoid paying the bills).

It would be inefficient if the Surgery department had to collect from you the information it needs to find your medical record and orders; then have your surgical procedure followed immediately by a visit from the billing department to collect the same information about you so that they could proceed with coding and billing processes.  This clearly does happen sometimes.  Occasionally with good cause, but often because of redundancies between systems, and sometimes because the process doesn't think to collect a piece of information up front.  For instance, Admitting may not have any reason to ask "do you have any allergies" because that isn't necessary to complete their assignment of "log that the patient arrived and notify surgery."  So, Surgery has to ask the additional questions that are important to it "have you eaten," "do you have any allergies," etc.  With some of those questions, significant time and safety risks could be avoided if they are asked as early in the encounter as possible.

So, it seems to me that Enterprise Information Management is most importantly about the management of the edges of that graph and has a direct impact on the efficiency of the Information Supply Chain.  Those edges between the nodes of the diagram aren't merely straight lines that magically move information from one business process to another.  They are interfaces and systems and business processes that cost significant time, money, and risk to quality.

Why can't we expect each business unit to simply do what will result in an optimal collection and movement of information?  Not because they're maliciously selfish about their time or resources, but because individual business units don't usually have the perspective to fully understand the down stream value of their own operations.  Enterprise Information Management is the work that lives in between business units and drives overall optimization of the edges between them.  Enterprise Information Management is something that lives between and outside of individual business units.  Business units can be counted on to optimize their own internal operations.  Enterprise Information Management has to be planned and managed explicitly, above and beyond departmental objectives.

Thursday, February 4, 2010

How Not to Clean Data

PREFACE: Even if you don't have some familiarity with the inside of a hard drive, you'll probably still be troubled by this story from my past.  To answer the obvious questions that you'll have after the story: Yes, I really do have a legitimate degree in Electrical Engineering.  No, don't worry, I've never been employed in a way that uses that degree in a significant way to design or build any products that you might own.


I once had an old hard drive that started making a bit of a racket.  It didn't stop working right away, but I was concerned that there was something wrong with it.  I thought that maybe I could figure out what was wrong if I opened it up and poked around inside.  At that point I'd never seen the inside of a hard drive in real life.  So, I invested in my first set of star-point screw drivers and carefully disassembled the case of the hard drive.  Even after the screws were out, the metal cover stuck a bit.  It seemed like there was some kind of seal that had it closed, so I used a flat head screw driver to pry it open.

Wow.  Shiny.  Really clean.

I plugged the hard drive back in, while both the computer case and the hard drive case were open, and booted up the computer.  Cool.  It spins!  I watched it spin up, and the computer boot.  Everything working great.  That little moving arm is really neat, too.  It bounces back and forth really quickly!  So, I ran some programs on the computer and started listening for the noises that I thought were signifying an imminent disaster.  The hard drive just sounded rough.  Something like ball bearings worn down or the spindle just getting sticky.  Logically, I got out my WD-40, with the little red straw to make sure I could target the center of the spindle.

Squirt.... Squirt... drip, drip.

Well, let's see if this works for a while.  Maybe that was enough to quiet the drive down.

Things working fine.  Then the head did a seek and ran right through a drip of WD-40 and smeared across the platter.  Is that bad?  Then the actuator arm started thrashing back and forth, clicking hard against the center of the spindle and back against the outer wall of the case.  Clunk.  Clunk.  CLUNK.  Whirrrrr..rr...r....  Quiet.  Computer locked up.  Hard drive stopped.

Uh oh...

Maybe if I clean that WD-40 off of the platter it will work again?


So, I got out my trusty Goo Gone and a soft rag to remove the extra drips of WD-40 that were now smeared across the top platter of the hard drive.  Rub, rub.  Wipe.  Rub, rub.  Polish.  That looks pretty good.  Let's spin it back up and see.  W....h...i.rrrrrrrrrrr.  OK, that sounds pretty.... CLUNK.  Clunk.  Clunk.  Clunk.  Unplug the computer.

I worked on this for a couple of hours.  I used more Goo Gone.  I used alcohol -- both the rubbing kind to clean the platter and the drinking kind to calm my frustration.  In the end, I was able to get the drive spun up long enough to retrieve some files.  This was still an age when most of my working documents were on floppy disks, because I needed to carry those between different computers.  So, luckily, there was no important data lost.

I've been thinking a lot lately about how "broken" business processes impact data quality and data integrity -- thinking about the ways we look at trying to keep the data inside those disks clean and running smoothly.  Sometimes we look at things from a perspective that is too distant, with a too limited understanding of the context of the processes that we're examining, and act too quickly and too inexpertly without taking time to understand the nuances of the systems and business processes involved.  We do things that we think will help (implement governance processes and quality screens) and end up sending the system into a tailspin.  Things do recover from that dive, but not without a major investment in time and energy.

Wednesday, February 3, 2010

New Magic Quadrant for DW DBMS

Gartner released it's new Magic Quadrant for Data Warehouse DBMS platforms.  I tend to think that Gartner does a reasonably good job with its Magic Quadrant results.


Here's my personal summary.
  • Oracle holding on to 2nd place for enterprise data warehousing with its "reference configurations," Exadata product, and 11g upgrade as prominent strengths; downside being claims of higher DBA FTE cost than some other DW platforms.
  • Teradata remaining the clear leader and probably expanding their market presence with newer pricing model and platform options.
  • Microsoft lagging far behind the other big vendors while it tries to integrate the technology it purchased with DATAllegro in 2007.
  • My favorite aspiring open source vendor, InfoBright, sitting in the middle of the of the niche quadrant as a brand new entrant.

Full disclosure: I don't own stock or have a personal stake in Gartner or any of these companies.  I've personally developed or managed large data warehouses on DB2, Teradata, and Oracle.

Tuesday, January 26, 2010

Simplifying != Lying


The Unified Modeling Language defines a lot of different mechanisms or views for documenting the structure and behavior of a system.  As you move your way through them, they provide greater levels of specificity or higher levels of abstraction.  I worked on an effort several years ago that employed a set of UML-like standard views to describe a set of key applications.  In that effort, the set of views were labeled Contextual, Conceptual, Component, and Deployment.

The Component and Deployment views came straight from the UML standard.  The Conceptual view followed somewhat from this Wikipedia definition, but extended beyond the entity-relationship domain to include processes in something of a data flow.  The Contextual view was used to describe the surrounding business processes, actors, and external systems that interacted with the application or system being described.

It was a challenging exercise to work through the application systems that I was responsible for and document them appropriately, without overdoing the documentation.  Personally, I found the exercise very satisfying.  It helped me prove out my understanding of the systems I worked with.  Often, I'd start with a middle-layer view, like the Conceptual or Component view, then work my way either down or up, iterating back and forth a few times to make sure the depictions remained consistent, honest, and valuable.
As a side note, that sort of iterative process of working non-linearly, both up and down between different levels of abstraction reminds me a lot of the YouTube videos I watched a while back when learning how to use an abacus.  If you aren't familiar with how to use an abacus for simple math, take a look.  If you're trained in traditional Western math, it'll be an eye-opener.

 When introducing the idea of these four views to subsequent teams, one of the biggest surprises has been the level of dishonesty that tends to appear in the higher levels of abstraction.  I've also found it hard to explain what it means to be dishonest about an abstract view of something. 

For instance, in a Conceptual view, I've seen people draw a box that is intended to represent one conceptual system when the box actually comprises two or more entirely independent processes.  For example, by this definition, it would be dishonest to diagram a single box labeled Item Master that has arrows sending data to separate operational systems if there is, in fact, no system or business process that actually manages a conceptually unified source for the item information in those systems.  Not that there has to be some physical thing or even one single source of truth, but if the item information is built separately in those two systems with no regard for the the other system, then it would be disingenuous to suggest there's even a conceptual idea of a single Item Master.  That's not to say that there should or shouldn't be -- but to document a conceptual view of that in the current state would be dishonest. 


I've seen this happen enough times that I believe there's some common confusion about what it means to build abstract models.  Simplifying how we look at something, using abstraction, should never result in a lie about how things actually work.

It's a lot like scientific mathematics 101.  Remember the lessons about significant digits and the difference between precision and accuracy?  Precision defines the degree of specificity and detail to which the answer is given.  A component diagram is more specific about the actual construction and inner workings of a system than is a conceptual diagram.  In order for them to be correct, both must be highly accurate depictions, though.  Losing accuracy during abstraction will only get you in trouble.

Friday, January 22, 2010

Slow Processing


When I was in grade school and junior high school, I was considered to be pretty good at math.  I went to math competitions all across the state and won 1st place more often than I didn't.  In most of the competitions, time didn't matter to the score.  It was a timed test rather than a race.  In my head, though, I needed to be one of the first to finish.  Being right was fine.  Being right and first?  That was really winning!  As you'd expect, that got me in trouble every once in a while.  I'd get sloppy on a couple of questions and not win 1st place.  Going back over the tests, I'd kick myself for not simply rereading the question a second time through.

My mother was the one who kept coaching me to slow down.  Read the question a couple of times.  Check your work.  I don't know if I've ever really learned the lesson to slow down and double check my work as much as I should.  If you've been reading many of my blog posts, I'm sure you've caught a plethora of typos.  Lucky for me, Firefox usually catches my misspellings.

Same lesson applies to how we process data for data warehouses.  Consider a somewhat typical batch ETL process:
  • Process input files:
    • Surrogate key lookups
    • Field level transformations
    • Calculations
    • Mapping to target tables
  • Load files into staging tables.
  • Apply updates and inserts.
Then, after the loads are complete, run a series of validation routines to ensure that all of the data that was received was actually applied to the target tables.  Total the input by some grouping; total the output by some grouping; and compare the results.  If things don't match, then send someone off to start digging through the data.

Certainly, that load process was very efficient.  Doing all those block level operations and applying large chunks of updates all at once, rather than doing one-record-at-a-time processing gets the data loaded to the warehouse much more quickly.  Bulk operations, reducing some of the transaction management overhead and improving I/O throughput, definitely do that.  Don't forget, though, that in order to feel truly confident that the processes completed successfullly, you have to read all of that data a second time to balance out the totals.

A slower alternative is to process the data more sequentially and validate that a single row makes it to each intermediate staging area or directly into the target table.  Create a process that watches every row get transformed and loaded, and reports on exactly which records failed to load rather than merely telling you that the final insert/update somehow came out 10 rows short of what was expected.

So, it seems to me the options are these:
  • "Fast" - load in bulk very quickly; do batch validation; if totals don't match, kick out for research and troubleshooting.
  • "Slow" - process each row more methodically and kick out exactly which rows fail any piece of the process.
There are complexities to this choice, clearly, and they depend on things such as the level of complexity in the ETL, the size of the batches, the available windows for processing, system usability during processing, etc.  The most important "slow" lesson is to examine the situation you're in and make a rational decision about how to process data and validate it is loaded correctly.  Don't make snap-assumptions about the right way to ensure data integrity on any particular process.

Wednesday, January 20, 2010

BI for MBA students

I've got the opportunity in 6 weeks to guest lecture for one eventing to an MBA class about Business Intelligence systems.  The course is a general Information Systems class that the MBAs are required to take, so I'd like to make sure the conversation does an effective job engaging them and helping them understand the role systems and technology play in supporting decision making.  Any thoughts or advice on important things to make sure I cover in 2 hours?

Post a comment or tweet @paulboal.

Tuesday, January 19, 2010

Stand Slow

As the title of this blog shows, I'm a big R.E.M. fan.  They're great performers, and I've always loved their lyrics.  Thinking about what it means to me to slow down, the lyrics to "Stand" seemed appropriate.
Stand in the place where you live
Think about direction
Wonder why you haven't before
Now stand in the place where you work
Think about the place where you live
Wonder why you haven't before


If you are confused check with the sun
Carry a compass to help you along
Your feet are going to be on the ground
Your head is there to move you around


If wishes were trees the trees would be falling
Listen to reason
Season is calling


Stand in the place where you are
Your feet are going to be on the ground
Your head is there to move you around, so stand.
I want to highlight a few of the lyrics in the context of what it takes to do effective technical analysis and design activities.


"Stand in the place where you live"
Start the work at hand by examining it from an internal perspective.  Look at the data, process, or system from the context of someone who really knows it well.  Learn from them some of the intricacies of how it's put together and how it behaves.  These are the people who really live with the system day in and day out.

"Stand in the place where you work.
Think about the place where you live."
Now look a the data, process, or system from the perspective of someone who is a user or consumer of it.  Get their perspective on how things look from the outside of day-to-day life of supporting and maintaining the thing being analyzed.  The important this is to get outside of your own skin and try to look at things from alternate perspectives.

"If you are confused, check with the sun.
Carry a compass to help you along."
Remember that the title of this song (and every third word) is "stand."  We need a vision and guiding principles in order to know that, as we dig deeper and deeper into the weeds of a project, we don't lose sight of what the driving purpose is.  Remember, when you get down into the weeds, it may seem easier to follow the goat path that someone else already pushed down rather than following the sun (vision) and your compass (guiding principles).

"Listen to reason; reason is calling."
As Jim Harris (ocdqblog) reminded us at the beginning of the year with, "Shut Your Mouth," there's high value to be found in learning to listen.  It can be difficult to know how long to listen before starting to draw conclusions and respond.  It's good advice to to listen even more closely as things seem to sound ridiculous.  For example, I was in a conversation once that described how a payroll process worked.  I was flabbergast by the amount of special logic that went into the business process.  It seemed ridiculous.  Then, I listened harder and further into the conversation (and asked some open-ended questions) to really understand.  As I understood more and more about what I thought was a ridiculously complex process;,

"Your head is there to move you around."
Key emphasis on head.  You should make decisions based on the thoughts in your head, not on your gut feels running around in circles.

Thanks to Stipe and company for the song!

Monday, January 18, 2010

Slow and Agile

I first read the Agile Manifesto nearly 8 years ago.  Anyone familiar with agile principles understands that one of the underlying goals is to produce better solutions, faster, with less wasted energy along with way.  Anyone familiar with introducing agile practices to an existing team knows that agile works best with strong individuals.  Read the manifesto with that in mind (their emphasis, not mine):
Individuals and interactions over processes and tools
Working software over comprehensive documentation
Customer collaboration over contract negotiation
Responding to change over following a plan
I want to be clear - I'm am a strong support of the agile philosophy.  For those of you out there who, like me, would rather spend your time interacting with a computer rather than a human being at work, I want to to point out that agile relies heavily on human-to-human interaction and a high degree of trust in team members and stakeholders.  Key words: individuals, interaction, collaboration.


This is where being slow becomes so important.  Clear communication requires both the sender and receiver of the communication to be very intentional.  "Need the system to do X."  "Got it!"  Is not an effective interaction.  Both parties have to slow down the pace of their interaction in order to be intentional about what they're communicating and make the practices effective.


Speakers:
  • Studies show that we have to repeat ourselves in order for effective comprehension to take place.  Tell the listener what you're going to say; say what you're saying; tell the listener what you just said.
  • Look for comprehension, both verbal and non-verbal: head nodding, eye engagement, note taking, clarifying questions.
  • Provide opportunities for questions.  Some listeners may not be great at asking questions up front, so give them ample time.  Pause after significant points or topics that may be unclear.
  • Validate the receiver's understanding.  Ask for comprehension about specific points, not just a general "does everything I said make sense."
  • Listen and watch for when the receiver flinches, raises an eyebrow, takes extra notes, or tries to break into the conversation.  What you think is already clear is the mostly likely place for miscommunication with someone unfamiliar with the topic.


Listeners:
  • Listen actively.
  • Confirm the assumptions that you have about the topic going into the conversation.  You and the speaker may be starting from different places.
  • Validate assumptions you have with what the speaker is telling you.
  • If something the speaker says doesn't sound right, that's a clear sign that there's some misunderstanding going on.  Either one of you is actually wrong in the information (in which case, facts need to be validated and clarified for both parties) or the communication is not working effectively.  In either case, ask questions and clearly state your assumptions in order to clarify.
  • Repeat what you're hearing back to the speaker in your own works.  Become the speaker and look for their honest confirmation that you've understood them.
  • State any conclusions that you've drawn from the conversation.  They're likely based on both the information in the conversation as well as other unintentional assumptions.
  • Confirm the action items, changes, or impacts of the conversation.  Describe what it is that you think this conversation means to the project; and ask the speaker that same question.
Agile is pro-change (so to speak) in that it doesn't fear changing needs.  I believe that the message in that point of the manifesto is to encourage teams not to fear change and to be willing to build what is needed rather than what is written in out-dated specifications documents.  The key there is that the team is working to build what is needed.  Whether we're building from technical specs or from personal interaction, effective communication and collaboration are required.

So, make sure you take communication slowly and intentionally.  Emphasize communication performance, not just responsiveness.[1]


[1] As a little more detail on that footnote, I think the Wikipedia entry for "responsiveness" makes a great point about the difference between performance and responsiveness.  In that example, the point made is that for usability, it makes sense to put the mouse driver at a higher priority than background processing so that the user experience is more pleasant.  In an interview, though, the background activity of comprehension needs to have plenty of processing time.  The verbal back-and-forth of the conversation can take a decreased priority to ensure that good understanding is happening.

Friday, January 15, 2010

The Power of Slow

I spent part of my work day today doing mid-year reviews with my staff.  For us, it's merely a mile marker in the year, not any large event.  I meet with each member of my staff on a weekly basis formally as well as in ad hoc drive-bys throughout the week.  It works well to maintain that consistent and continuous communication.


During one of these 1-on-1 meetings today, one of my architects was voicing some frustration about the attitude a few project leads were taking with him.  They were pushing the team to just hurry up build something.  Whatever they could do quickly that worked.  He was saying that he had a hard time describing to these project leads how a touch more patience and even a different attitude about the definition of progress would help them see the risk in their approach.

I mentioned to him that I've been slowly reading Carl Honoree's The Power of Slow since last summer.  Only in that moment did I realize there was a way of expressing "slow" to addictively "fast" people.  Slow isn't about taking more time to get things done.  Slow is about the internal pace at which things are done.  From a software architecture perspective, slow doesn't mean spending months in design before anything is built; it means taking the time as your write each class and method to think through how best to write that particular class or method.  It isn't about wastefully over-engineering the solution to be something that will "be scalable into the future for unknown other uses" while the immediate problem is left unsolved.  It's about being methodical and intention in each action we take.  That creates a slower appearance, because the process becomes more efficient and there's less waste moving up and down the rate of progress curve.


The "Slow" line represents a steady and consistent stream of work.
You can think of the dips in the "Fast" line as any number of things:
  • Hurry up, then wait
  • Work fast, then go back to fix your mistakes
To reach the 100% mark at the end of the chart, both approaches may get there in the same amount of time, but the "Fast" approach consumed a lot more effort.  Effort being the length of the line itself.


One of the fears that a "fast" people have, especially "fast" managers, is that "slow" implies developing ultra-sophisticated solutions, most of which will never actually be used; over-engineering; or architecture-creep.  For some "slow" people it probably does, but the right kind of "slow" is merely a thoughtful, methodical implementation that gives everyone enough time to make sure they're doing the next step in the project correctly.  I may feel slow, but that's only because it's efficient.


Ironically, we see this in the world around us all the time.
  • When starting your car from a stopped position on slick slow or ice, you have to do so slowly or the wheels will merely spin.  In both cases, you'll move forward some, but when accelerating too quickly, you'll burn a lot more fuel and tear on your tires.
  • In cartoons, we see the antagonist rushing around in a hurry from place to place, rushing; while the protagonist slowly and thoughtfully moves through the chaos and reaches the goal first.
  • In action/comedy movies, we see a brash martial artist execute a flurry of activity in a dramatic attack, only to be stopped by a few small simple motions of the hero.
So many people incorrectly think that looking productive is the same as being productive.

In my own writing, my wife points out to me that there is power in brevity.  Sentences should say all that they need to say and no more.  I tend to add too many unnecessary adjectives, or flourishes, or sentence complexities.  More words often doesn't imply more meaning.

Tuesday, January 12, 2010

The Role of Health Informatics

Interesting question that's always puzzled me is what is the differentiation between the term "informatics" and "information management."  In my admittedly limited experience, informatics is used primarily in scientific and medical fields, such as "health informatics".  Information management is a more general business term.  Why different?

For one thing, I suppose, the etymology of "informatics" explains part of it.  The "-ics" ending means "the science of."  So "informatics" is the science of information rather than the management of information.

The Wikipedia article defines "health informatics" as having these key aspects:
  • Architecture for electronic medical records and other health information systems
  • Clinical and other health related decision support systems
  • Standards for integration
  • Standards for terminology and vocabulary

Food for thought - In the health care industry, does it make sense to co-locate business roles like master data management, data quality, information integration, and business intelligence with the traditional informatics departments; rather than building them within business management units or IT/IS units?  Does asking health informatics to work with other non-clinical business functions somehow risk or distract from patient care responsibilities?

(As a side note for those across the pond, it turns out that "business informatics" is a European term, closely related to "information systems" study, but with some subjective differences pointed out in the Wikipedia article.  It is not a term commonly used in the U.S.)

Friday, January 8, 2010

Organizational Optimization


I'm not an expert in business organization design or organizational optimization, though have been an active decision-maker in a few organization redesigns and layoffs (I'm sad to say the latter).  It seems to me that the rules of what a business looks like, organizationally, could follow some of the same basic guidelines that enterprise architects and software architects use for the design of a large system of applications.

Clarity of Purpose
A business unit must have a well defined purpose.  It should be clear to the rest of the organization what the function of the business unit it is, so that other business units know when to engage with it, what information it has/creates/uses, and what purpose it serves.

Well Defined Interface
A business unit must be clear to the larger organization on how to interact with it and expectations the organization may have with regard to service completion time or delivery schedule.


Value
A business unit must be able to readily respond to questions about its value to the bottom-line performance and goals of the larger organization.  If it's value is not sufficient to outweigh alternatives, then it is irresponsible to continue to use it.  The lower cost alternatives should be used.

Reliability
A business unit should either be self-sufficient enough to achieve its purpose alone, have plentiful access to external services such that they are unlikely to be a limiting reagent, or have sufficient influence over the priorities of external services such that they will not hinder progress.  If the business unit is unable to make those conditions occur, then it will suffer from inefficiencies and risk not being able to achieve it's goals.

I think that's very consistent with system/software engineering principles laid out in the Unix philosophy.
  • Do one thing and do it well.
  • Write programs that work well  together.
  • Data dominates. If you have chosen the right data structures and organized things well, the algorithms will almost always be self-evident. Data structures, not algorithms, are central to programming.
  • Fold knowledge into data.
  • Design for simplicity.  Add complexity only when you must.
The time-value curve also could be use to help design organization principle.
  • Organizational structure should optimize the amount of time between an event and the decision making and action that will result from that event (opportunity is lost in the interim).

Tuesday, January 5, 2010

Canned Solutions Canned

Or: 
Why we need more data professionals employed with health care providers rather than health care consultancies.


I'm a member of a health care provider industry association that shares information across organizations about our experiences delivery business intelligence and data warehouse solutions.  Recently, one of the members of that organization posted a forum question about several packaged industry-specific data warehouse solutions that they'd had pitched to them.  Here was my response.  I thought it was worth sharing here as well.

My personal experience (as a BI/DW consultant and professional for the past 10 years) is that prebuilt data warehouse solutions for any industry come in three flavors:
  • Logical-only models that come with an implementation "project."  The physical implementation will be built to suite your organization and usually use language and terminology that your organization is comfortable with.  These are full blow projects.  Though some ideas come in the box, very little runable code is ever included inside the box.  That takes the time and money of professional services.
  • Canned data warehouses / data marts that come as a full blown, predefined solution.  These might seem like a good idea because so much is already built for you.  In my experience, though, they return only a fraction of the business value they seem to promise, though.  The model in the canned solution doesn't typically match your own business model closely enough to be as valuable as it appears during the sales meetings.  Another challenge with these solutions is the integration of data into them.  They're either so high level that they don't have a lot of value; or they're so different from your own organization that the mapping of data into their model is overly complicated.
  • Marketing hype - in some cases, the solutions really are just a marketing message.  In reality, the vendor is merely saying "We have some people from health care and we have some BI skills.  We've put them together on a team for you."


That's not to say vendor solutions aren't a reasonable way to go for you.  When you talk with them, be very specific in your questions and very critical.  Ask to talk with other client references that are similar in size, systems, and market to you.  Do a proof of concept to implement some small portion of the solution free of charge.

I hope I don't sound too harsh on vendor solutions in that response.  I don't believe that vendors intentionally oversell their solutions.  In some cases, they're ignorant as to what it takes to really build, deploy, (and most often) run, maintain, and enhance a data warehouse for several years after the initial implementation.  This was one of my personal realizations as I transitioned from consulting into a corporate job.  Other vendors may simply being putting the cart before the horse, and using consulting opportunities to build up their solution offering.  No harm in that as long as they're upfront and honest about it.

On December 30, 2009 HHS presented the much anticipated details of the definition of meaningful use of electronic health records.  This definition provides more information about the level of functionality and use health care organizations must achieve by certain deadlines in order to receive certain types of government assistance and maintain the highest levels of medicare reimbursement.  (I have not read the details.)  Soon there after @theEHRguy tweeted a couple of great predictions:


I think it would be better if we paid those of us who actually work for health care organizations $450/hr.  Unlikely.

Still, I think he makes a very good point about consulting services, and I'd extend that to certain types of packaged vendor solutions by nature of the services they usually imply.  The high demand in the area of health care systems right now is going to be shortly followed by a high demand for BI/DW solutions in the same space.  In the rush, I think the industry risks implementing poorly designed packaged vendor solutions will result in a lot of wasted time, money, and effort; and lost opportunities for growth and optimization.  Time will tell, but I think it's a long road ahead.

Sunday, January 3, 2010

Who's data is it? (Part 4) - Counter-Point

The past three posts in this series have dealt with negative behaviors or attitudes about the responsibility of data ownership:
  1. It's the vendor's data
  2. It's MY data
  3. It's NOT my data
As I mentioned a the end of part 3, an important factor to consider when looking at any of those situations is the history behind how the team or organization came to be where they are.  Every organization forces behavioral pendulums to swing back and forth between extremes in response to negative outcomes.  What might appear to currently be a negative behavior may have once been a reasonable response to some other negative experience.

For instance, "it's the vendor's data" may well have developed in response to some historical data conversion or data integration project that well over schedule and over budget because data structures were poorly understood by the internal team and the use vendor services was discovered, too late, to be a huge benefit.


Likewise, the "it's MY data" crowd might come from an application support team that has come to understand the value of information integrity and master data, and has developed a sense of protectionism from those goals the hard way: by failing to meet past goals.  "We're responsible for maintaining CUSTOMER data for the company.  If someone else starts using that data without our close direction, then they'll misunderstand what they're looking at and misuse the data."

The philosophy behind this perspective is very reasonable, but the implementation becomes one of closing off access to information rather than increasing and easing accessibility and educating users and other teams on how data should be used.  Rather than maintaining institutional knowledge exclusively within a support team, how to use key information should be exported to the larger enterprise.

People who are focused on executing business processes tend to examine technology and information management from a localized context: what information does this  process need as input and what applications will this process use?  This siloed view lacks the concept that a great deal of value comes from examining the space in between business processes or applications.  In the space between various business applications, there exists an opportunity to gain a higher-level of understanding about information interrelates between those various silos.

Conclusion:
Thanks for joining me on this conversation about data ownership.  Personally, I detest the word "ownership."  It has negative historical connotations that somehow suggest to me "ownership of data" implies the "enslavement of data."  But I struggle to find a more appropriate way to refer the concept that someone has certain responsibilities when it comes to managing information.

Perhaps it's a bit trite, but to borrow from the famous Native American proverb about the earth:

We do not inherit data from upstream systems; we provide information to downstream ones.

Friday, January 1, 2010

Who's data is it? (Part 3)

In the first two parts of this series on negative attitudes on data ownership, I talked about protectionists who want to keep tight control over who has access to what data.  The most important negative consequence of that attitude is that it stifles both understanding and innovation. Fewer people looking at data means that the data is being examined from fewer perspectives.  Innovation comes from looking at existing situations or information from a new perspective and reaching new conclusions.  So, one of the best ways to confront data protectionists is to put the argument in terms of that business driver: innovation and resulting improvements.

It's NOT my data...

The final negative data ownership pattern I'll present in this series is the "it's NOT my data" attitude.  In this scenario, people within the information supply chain simply abdicate responsibility for anything regarding information, beyond their immediate operational duties.  This can manifest itself in several ways.  With respect to data quality concerns, the "not my data" crowd will simply point their fingers upstream:
  • "That's what's in the system."
  • "That's what the sales team entered."
  • "That's what the customer told me."
All of these are only excuses for poor data quality.  By themselves, they do nothing to address data quality problems.  These are reflective of a culture that doesn't look beyond the operational duty of data entry and service or product delivery. 

A more subtle manifestation of the same attitude might look something like "You can have the data, but don't ask me what it means.  You'd have to ask so-and-so about that."  And when you ask "so-and-so" he directs you to "what's-her-face," who tells you to ask her supervisor, who explains that they're just doing it the way the Standard Operating Procedure tells them to.  In this chain of inquiry, everyone is abdicating their own responsibility to understand how their work fits into a larger picture.  It's a form of willful ignorance.

In his motivational work, Christopher Avery uses a model for responsibility that describes several responses that all come before actually taking responsibility for a situation:
  • Denial
  • Lay Blame
  • Justify
  • Shame
  • Obligation
In the "not my data" culture, groups are stuck in one of those first three levels: denial, lay blame, justify, or shame.  They either deny that there is anything to even consider with regard to data ownership and data quality; they lay blame on other constituencies that are upstream from them (even all the way to a customer!); or they justify the situation, telling themselves that there simply isn't another way that things can be done.

The engineer in me sees a certain appeal to "not my data" situations.  In the extreme, they're a great challenge in reverse engineering.  Every steps yields more questions than it answers, and opens new places to explore for broken processes and more denial of responsibility.  It's like a software debugging exercise that leads you into deeper and deeper through twists and turns of function callbacks until suddenly you discover that critical nugget of information that finally allows you to describe the end to end flow of information, and the real impacts of poorly implemented processes or policies.

The real-world corporate director in me sees situations that need to be addressed, supervisors to be educated or replaced, policies and procedures to be changed -- all great places for change and growth -- but also, much less enthusiastically, politics to be navigated.

Counter-Points...
There are always multiple perspectives to any situation.  Teams and organizations don't usually evolve what may appear as negative attitudes out of ignorance or malice alone.  Often, other negative influences or behaviors lead to a culture that once served a valuable purpose, but may no longer yield more benefits than harm as the previously negative influence dissipate.  The final in this series will present situational counter-points to some of the arguments I've presented.

Wednesday, December 30, 2009

Who's data is it? (Part 2)

In the first part of this series on who's data is it, I talked about the black-box mentality that some teams have with regard to vendor applications.  In that scenario, the hurdle to overcome is primarily one of convincing the right authorities to grant you database access.  That's the biggest hurdle, assuming the application data is actually understandable once you get at the underlying database.  Unless the application team is more loyal to the vendor than to your company, you haven't burned any important bridges in that scenario.  The vendor won't support your efforts at extracting and integrating data from the application this way, but they're the one's who put out a ridiculously high $250,000 bid anyway.  The next scenario is more politically charged, however...

It's MY data!

The "it's my data" culture sees the information behind an application as something that needs to be closely held and funneled through a controlled group of experts.  Unlike the vendor-data perspective, the my-data group is interested in sharing information outside of the application interface, but often with point-to-point interfaces that they can tightly control (as opposed to any kind of pub-sub or hub-spoke model that creates a more open access model).  They're interaction often sounds like: "You provide exact specifications with which specific fields you want and we'll send you an extract with exactly that information."

Another common response from application teams to a request for access to an application database might be something along the lines of "what are you going to do with that data?  We have responsibility for that data and it can be very complicated to understand."  This kind of response is indicative of a belief that the application team has some kind of exclusive ownership of the data and should be the only group allowed to parcel information out to users individually through reports or extracts.  At the extreme, it's reminiscent of early reporting days where a user would call someone in IT for a report; that IT person would build the program to generate the report; print the entire report on green-bar paper; and then send it through interoffice mail to the requester.  If the application team isn't already on board with a service oriented approach to exposing data to other applications or integrated reporting through data warehousing, then their natural tendency will be to create a plethora of individual point-to-point solutions across the application landscape.

This kind of architecture may lead to well defined standards and definitions of data, but either only in pockets across the organization or with an ever increasing cost of maintenance as the number of interfaces expands and complexity of that interaction increases.  There are some positive aspects to a culture that wants to protect the purity of its data and have a strong understanding of how other groups are using the same data.  Part 3 of this series will touch on that data purist counter-point.